A release can pass its tests and still be unready to ship. In a survey reported in LaunchDarkly's AI Control Gap Report, 82% of teams had shipped changes with unresolved risks under delivery pressure. Test completion doesn't tell you whether those risks are contained, whether customers will notice a failure, or whether the on-call engineer can recover safely.
The useful distinction isn't under-tested versus well-tested. It's under-measured versus evidenced. A green dashboard means little when nobody can identify which journeys passed, which artifact was tested, what performance threshold applied, or who accepted an unresolved defect.
A release readiness checklist should replace those ambiguities with objective pipeline gates. Each gate needs a named owner, a pass criterion, evidence tied to the release candidate, and a rehearsed response when something fails. Automated checks should enforce repeatable rules; human approvals should address explicit risks, not compensate for missing results.
Release rule: Missing evidence is not a pass. A waiver is an accountable risk decision, not a green test result.
These gates don't require identical testing for every change. A copy update and a payment migration deserve different validation depths, but both need traceable decisions. Every gate below can either run automatically in CI/CD or attach verifiable evidence to the deployment record.
Table of Contents
- 1. Critical User Journey Coverage and Passing Smoke/Regression Suites
- 2. CI/CD Pipeline Quality Gates
- 3. Performance and Load Testing Against Baseline Thresholds
- 4. Security Scanning and Risk Review of Critical Flows
- 5. Observability, Monitoring, and Alerting Readiness
- 6. Rollback, Feature Flags, and Progressive Delivery Plan
- 7. AI and LLM Output Validation, Safety Checks, and Guardrails
- 8. Release Documentation, Go/No-Go Decision, and Stakeholder Sign-Off
- The 8 Release Readiness Gates at a Glance
- Ship on Evidence, Not on Hope
1. Critical User Journey Coverage and Passing Smoke/Regression Suites
Start with what customers must be able to accomplish, not how many tests the repository contains. For an online store, that means signing in, finding an available product, paying, and receiving an order confirmation. Testing each screen separately won't prove that the order reaches fulfillment.
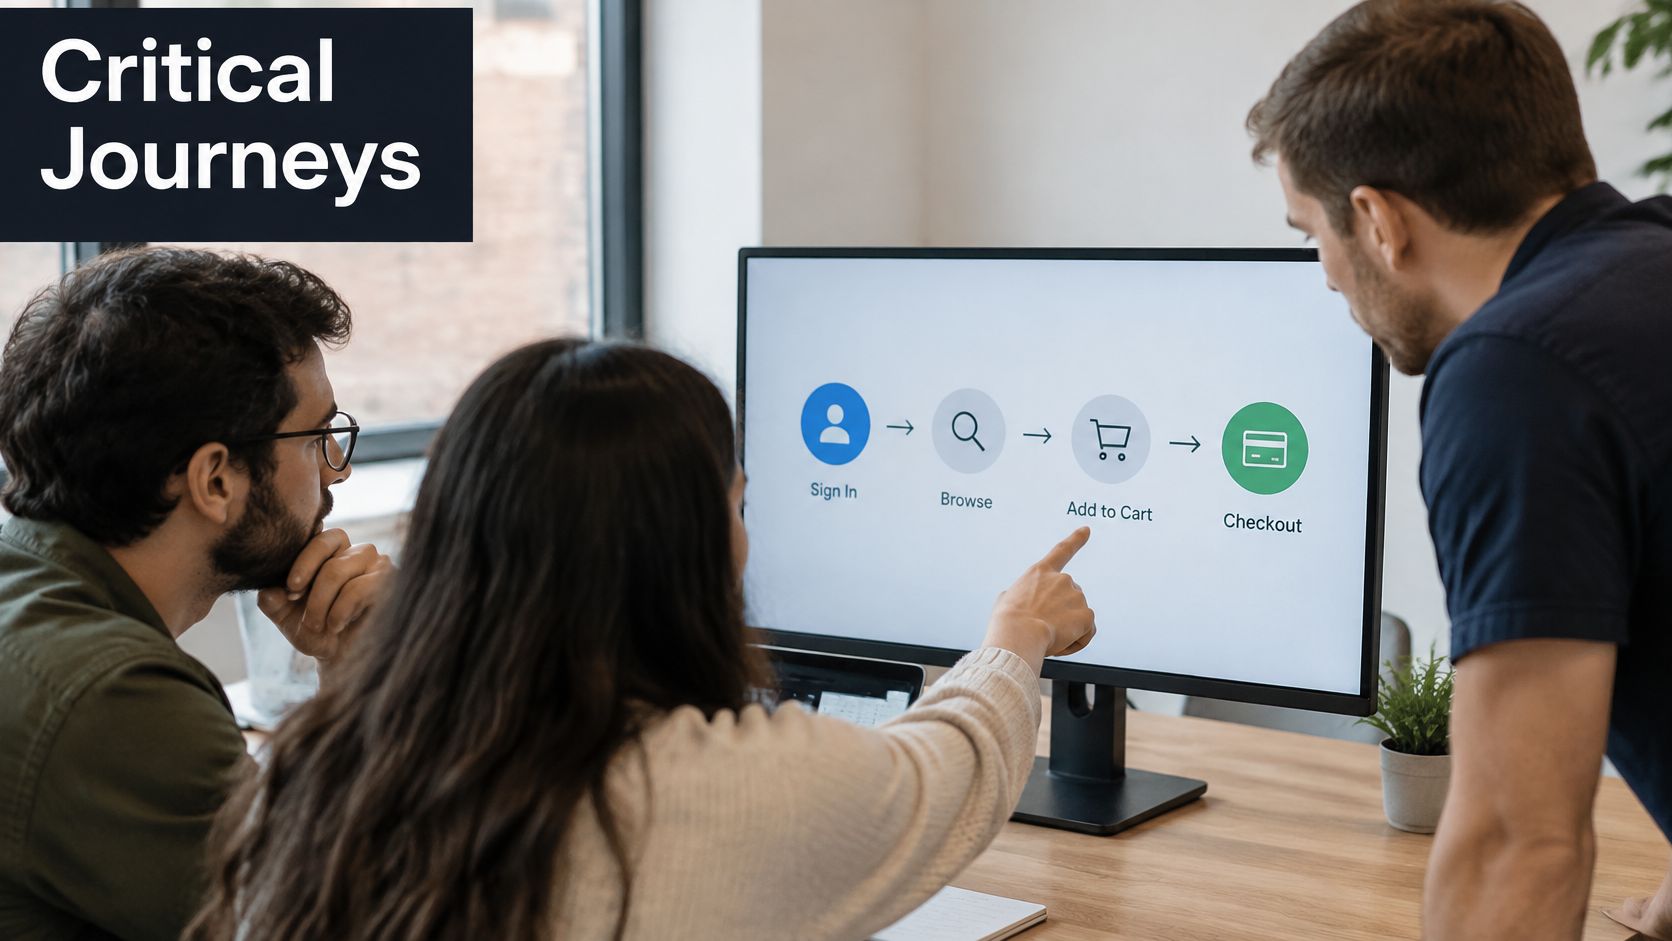
QA should maintain a journey-to-test map that connects business requirements to executable checks. Include supported browsers and devices, permissions, important failure paths, and accessibility checks for critical interactions. When scaling delivery for health tech teams, apply that same mapping to sensitive workflows such as accessing records and preserving authorization boundaries.
What closes this gate
- Pass criteria: Every required critical journey passes against the identified release candidate, with no unresolved blocking defects.
- Evidence: Store the build identifier, environment, test-data version, results, and failure artifacts together.
- Failure response: Stop promotion, reproduce the failure, fix it, and rerun the affected journey plus related regression coverage.
Keep the smoke suite shallow and decisive. Use Playwright for browser journeys, API checks for backend state, and Appium where native mobile behavior matters. Run deeper regression checks before promotion, and invalidate relevant results whenever the candidate changes.
The common failure mode is rerunning until green. If checkout passes intermittently, you don't have reliable evidence that checkout works. Quarantine a flaky implementation only after replacing its critical coverage with another dependable check, then assign a repair owner.
For recovery rehearsal, deliberately break a staging dependency and confirm that the suite blocks promotion with useful diagnostics. A failing test that nobody can diagnose quickly becomes a tempting override.
2. CI/CD Pipeline Quality Gates
A developer shouldn't be able to deploy an artifact that bypassed the checks everyone agreed were mandatory. Configure GitHub Actions, GitLab CI, or Jenkins so required jobs control promotion, rather than merely publishing reports someone might read.
Google Cloud's 2023 State of DevOps report announcement identifies change lead time, deployment frequency, change failure rate, and failed-deployment recovery time as foundational delivery measures. Use them to assess whether your gates support delivery without sacrificing operational stability.
Promote the tested artifact
Run linting, unit tests, secrets detection, and static checks early. Follow with integration tests, candidate deployment, smoke coverage, and the slower checks justified by the change. A practical CI/CD pipeline test automation approach places checks where their feedback can still change the release decision.
Pass criteria: Every required job succeeds for the same immutable artifact, and production deployment references its digest. A skipped job, unavailable scanner, or missing report must remain incomplete, not become successful.
Say a fintech team builds a container after merge, tests it in staging, and promotes it to production. Rebuilding from the same commit before deployment breaks the evidence chain because dependencies or build inputs may differ. Promote the tested container instead.
An override should identify the failed criterion, approver, mitigation, and expiration. It should never erase the original failure.
Rehearse a failed runner and a missing artifact. The pipeline should stop safely, preserve logs, and resume from a known state after repair. Avoid creating so many low-value blockers that teams routinely seek bypass permissions.
3. Performance and Load Testing Against Baseline Thresholds
A checkout endpoint can return the right answer while taking too long to be useful. Performance readiness requires both absolute service limits and comparison with a representative baseline, not a successful load-test exit code.
For a retail release, use k6, Gatling, or JMeter to model browsing, basket updates, checkout, and payment callbacks together. Derive concurrency, arrival patterns, dataset size, and transaction mix from production behavior. A small database and evenly spaced requests can conceal expensive queries and burst-related failures.
Define the threshold before running the test
- User-facing limits: Require journey latency and error rates to stay within approved service objectives at expected peak load.
- Capacity limits: Check queue growth, connection pools, resource saturation, and whether throughput keeps pace with incoming work.
- Regression limits: Compare with a stored baseline under equivalent conditions, using a tolerance established from repeat-run variability.
Percentile latency matters because an average can hide slow experiences. Record the chosen percentile, measurement window, warm-up behavior, environment configuration, and baseline version in the test definition. Build these choices into your performance testing strategy, rather than negotiating them after a disappointing result.
Pass criteria: All approved limits hold, and the system returns to normal after load subsides. Store raw results alongside the candidate identifier so engineers can distinguish application regressions from environment changes.
The failure mode to watch is a short test that misses accumulating memory use or queue backlog. Run longer soak tests when changes affect caching, workers, connection handling, or resource lifecycle.
Rehearse recovery by reducing load, restoring the previous application version, and verifying that queues drain without duplicate processing. If recovery requires manually clearing customer work, that's a release risk, not routine cleanup.
4. Security Scanning and Risk Review of Critical Flows
Security approval needs more than a clean dependency report. A scanner can identify a vulnerable library while missing an endpoint that lets one customer retrieve another customer's invoice.
For a B2B API release, combine static application security testing, dependency analysis, secrets detection, and dynamic testing against staging. Then exercise authentication, tenant boundaries, privilege changes, file uploads, and sensitive data handling with accounts that have different permissions.
Separate findings from release blockers
Security should define blocking rules before candidate validation begins. Block unresolved critical and high findings by default, then assess reachability, exposure, and compensating controls through an explicit exception process. Lower-severity findings can still block when they affect a sensitive workflow.
- Pass criteria: Required scans completed, critical authorization scenarios passed, and every accepted finding has a named security approver and remediation deadline.
- Evidence: Attach scanner versions, dependency inventory, reviewed findings, tested endpoints, and exception records to the candidate.
- Failure response: Stop promotion, repair the weakness, and rerun both the scanner and the relevant exploit scenario.
For database-backed APIs, stopping injection before code ships means checking parameterized queries and unsafe query construction, not merely testing whether normal input succeeds. Use OWASP ZAP for dynamic checks and Semgrep or CodeQL for static analysis, while keeping targeted manual review for business-logic risks.
Security boundary: A clean scan doesn't prove that the right person has access to the right data.
Rehearse secret rotation and credential revocation in a non-production environment. Removing a leaked token from Git doesn't invalidate it, and rolling back application code won't revoke an exposed credential.
The trade-off is review depth. Spend deeper human attention on changed trust boundaries and sensitive flows instead of applying the same checklist mechanically to every file.
5. Observability, Monitoring, and Alerting Readiness
Before enabling a new payment endpoint, send a controlled failure through it. Confirm that the service emits a useful metric, logs enough context to investigate, and routes an actionable alert to the assigned responder.
That rehearsal proves more than the existence of a dashboard. Observability readiness means the team can detect customer harm and take the next action, including when the application appears healthy at an infrastructure level.
Verify the whole detection path
Track journey outcomes alongside service latency and errors. For checkout, distinguish successful order creation from an HTTP response that only confirms a request was accepted. Add release identifiers to telemetry so responders can separate candidate behavior from the previous version.
Use OpenTelemetry for traces and metrics where appropriate, then expose operational views through tools such as Grafana or your existing monitoring platform. Keep secrets and unnecessary personal information out of diagnostic payloads.
Pass criteria: New behavior is visible, alert routing has been tested, the on-call owner acknowledges responsibility, and every paging alert links to a usable runbook. Capture the pre-deployment baseline and define the observation window before rollout.
- Failure mode: Alerts fire on CPU utilization while customers experience failed transactions that nobody measures.
- Recovery rehearsal: Trigger a staging failure, follow the alert, identify the affected release, and execute the runbook without relying on its author.
- Production check: Run synthetic critical journeys after deployment and compare customer outcomes with the approved baseline.
Don't page on every unusual measurement. Page on symptoms that require action, and use infrastructure signals to diagnose the cause. If telemetry disappears during rollout, pause expansion until visibility returns; silence isn't evidence of health.
6. Rollback, Feature Flags, and Progressive Delivery Plan
A rollback command isn't a recovery plan when the new application has already written data the old version can't read. Separate code reversal, feature containment, and data recovery, then prove which response applies to this release.
The IBM explanation of DORA metrics connects delivery performance with failed-deployment recovery time and change-failure rate. That makes recovery capability part of release evidence, not an operational task to investigate after deployment.
Rehearse the failure you might actually have
For a schema change, use expand-and-contract: introduce compatible structures, deploy code that can coexist with the previous version, migrate data, and remove obsolete structures only after compatibility is no longer needed. Destructive changes may require a forward repair rather than an application rollback.
Pass criteria: The previous artifact is available, the recovery procedure has succeeded in a representative environment, and the measured recovery meets the service's approved objective. Assign a deployment owner and a separate decision-maker who can stop rollout.
Feature flags help contain application behavior, but they don't undo sent emails, external transactions, or corrupted records. Test disabled and enabled paths, verify production targeting, and give each temporary flag a removal owner.
A canary release should expand only when its latency, errors, and business outcomes remain within the approved bounds. Low traffic or missing telemetry means insufficient evidence, not automatic permission to continue.
Use this distinction when reviewing the recovery workflow.
For example, a billing change might be contained by disabling new invoice generation while keeping read access available. Rehearse that exact state, including how queued work resumes and how operators prevent duplicate charges.
Record rollback triggers before deployment. Don't ask an exhausted responder to invent acceptable customer impact while an incident unfolds.
7. AI and LLM Output Validation, Safety Checks, and Guardrails
AI-generated code and AI product behavior need different release evidence. Generated code still needs understandable review and conventional tests; an LLM feature also needs evaluation of variable outputs and the actions those outputs can trigger.
In survey findings covered by Express Computer, 81% of software teams had merged AI-generated code or tests they didn't fully understand. That's a reason to demand traceable validation, not to treat generated code as automatically defective.
Gate behavior and authority separately
For a support assistant, version the prompt, model configuration, retrieval setup, and evaluation set together. Include representative questions, missing-information scenarios, misleading documents, adversarial inputs, and requests outside the assistant's permitted scope.
- Quality criteria: Grounded answers meet the approved rubric, required structured outputs validate, and regression evaluations stay within accepted limits.
- Safety criteria: The assistant respects refusal rules, protects restricted information, and withstands the defined abuse scenarios.
- Action criteria: Tools enforce authorization independently of the model, and consequential actions require the appropriate approval.
Use prompt injection testing to exercise hostile instructions in retrieved documents, tool responses, and user messages. Don't rely on a system prompt alone to enforce an agent's permissions.
A support agent that drafts a refund explanation and an agent that issues the refund shouldn't share the same release threshold. Evaluate output quality separately from executable authority, and calibrate automated graders against human-reviewed examples.
Pass criteria: The versioned candidate meets the use-case thresholds, reviewers accept the evaluation evidence, and containment works. Traditional regression tests remain necessary for the application surrounding the model.
Rehearse disabling tool execution, switching to human approval, and restoring a compatible prompt-model configuration. Reverting a prompt may not reverse actions an agent has already taken.
8. Release Documentation, Go/No-Go Decision, and Stakeholder Sign-Off
The final approval should summarize evidence, not begin collecting it. Generate a release packet from pipeline results and issue records so engineering, product, security, and support review the same candidate.
Release readiness is shared work: the 2024 State of Testing survey reported that 81% of respondents said their teams have a say in release readiness. Shared participation still needs named decision authority.
Record decisions against criteria
The engineering release owner confirms artifact identity, deployment mechanics, recovery readiness, and operational coverage. QA confirms required journey coverage and unresolved defect status; product accepts documented customer-facing limitations. Security approves security exceptions rather than leaving them buried in a general approval thread.
Pass criteria: Every required gate has current evidence, every exception has an authorized owner, and the deployment record contains explicit approvals. An acknowledgement in chat isn't enough unless it identifies the candidate and decision.
- Release notes: Describe what changes, what remains unavailable, and whether customers must act.
- Risk record: List known defects, affected journeys, mitigations, owners, and exception expiration dates.
- Support readiness: Provide troubleshooting steps, escalation contacts, customer communication, and incident ownership.
Say a SaaS release includes a reporting feature whose export format changed. Functional tests may pass, but support still needs to explain the change and product must confirm whether existing integrations remain supported. That's a concrete readiness decision, not administrative cleanup.
Use the packet to plan safer production releases, with deployment order and recovery decisions visible alongside approvals. Rehearse an aborted release so the team knows who cancels announcements, updates support, and resets flag configuration.
If a last-minute change creates a new artifact, invalidate the affected approvals and rerun the relevant gates. Sign-off belongs to a candidate, not a calendar appointment.
The 8 Release Readiness Gates at a Glance
| Gate | Readiness Question | Key Evidence Required | Typical Failure Mode |
|---|---|---|---|
| Critical User Journey Coverage and Passing Smoke/Regression Suites | Do the highest-priority user journeys pass before release? | Ranked journey map; passing smoke and regression suites; tests linked to journeys | Critical flows are untested, or flaky failures are ignored |
| CI/CD Pipeline Quality Gates | Do automated checks pass before changes advance through the pipeline? | Defined thresholds; visible pass/fail status; release artifact audit trail | Slow or unstable checks encourage teams to bypass gates |
| Performance and Load Testing Against Baseline Thresholds | Does the application meet performance targets under expected and peak load? | Service-level targets; realistic load, stress, and soak results; baseline comparisons | Unrealistic tests or environments hide performance regressions |
| Security Scanning and Risk Review of Critical Flows | Are vulnerabilities and risks in sensitive flows identified and addressed? | SAST, DAST, dependency and secrets scans; targeted flow reviews; risk sign-off | False positives overwhelm triage, or business logic flaws go undetected |
| Observability, Monitoring, and Alerting Readiness | Can the team detect and respond quickly to production issues? | Metrics, logs, and traces; service dashboards; routed alerts; runbooks | Missing or noisy alerts delay detection or go unnoticed |
| Rollback, Feature Flags, and Progressive Delivery Plan | Can the release be safely contained or reversed if problems occur? | Tested rollback procedure; named owners; feature flags; compatible migrations; rollout criteria | Rollback is untested or blocked by incompatible database changes |
| AI and LLM Output Validation, Safety Checks, and Guardrails | Do AI outputs meet quality and safety thresholds for the intended use case? | Versioned evaluation sets; scored regressions; safety checks; restricted actions; human review | Evaluations are outdated, inconsistent, or miss harmful edge cases |
| Release Documentation, Go/No-Go Decision, and Stakeholder Sign-Off | Do approvers have the evidence and support readiness needed to make a release decision? | Release notes; readiness and risk summary; known issues; named approvals; support briefing | Sign-off becomes a checkbox exercise or documentation lags behind changes |
Ship on Evidence, Not on Hope
Turn the gates into a one-page go/no-go record attached to every production deployment. Keep detailed reports elsewhere and link to them; the decision view should show the candidate identifier, gate status, evidence, owner, and any approved exception.
A useful release readiness checklist lets another engineer verify the decision without reconstructing a meeting. If they can't tell which build passed or why a risk was accepted, the record isn't complete.
- Critical journeys: Required smoke and regression checks pass on the candidate.
- Pipeline integrity: Mandatory checks passed, and the tested artifact is the artifact being promoted.
- Performance: Representative load stays inside approved service and regression limits.
- Security: Required checks pass, with explicit approval for accepted findings.
- Observability: Customer outcomes are visible, alerts reach responders, and runbooks work.
- Recovery: Rollback or containment has been rehearsed against the relevant failure mode.
- AI behavior: Applicable evaluation, safety, authorization, and containment criteria pass.
- Decision record: Named approvers accept the candidate, its documented risks, and its rollout plan.
Keep pass, fail, incomplete, and waived visibly distinct. An approved exception may permit deployment under your policy, but it shouldn't make a failed criterion appear successful. Record the mitigation, acceptance authority, and conditions that would require stopping the rollout.
The gates don't all need to execute serially. Run independent security, functional, and performance work in parallel where the environment supports it, while preserving prerequisites such as artifact identity and stable test data. Automate evidence collection so people spend their time reviewing consequences rather than copying results.
After deployment, keep the release open through its defined observation window. Confirm production journeys, customer outcomes, and service health before declaring success. When a production defect escapes, identify the missing signal and improve the relevant gate instead of reflexively adding more end-to-end tests.
Review the checklist when repeated waivers or noisy failures appear. Sometimes the answer is better coverage; sometimes it's a repaired test environment, clearer ownership, or a smaller deployment. A gate that everyone bypasses needs redesign, not another reminder.
We bring 15+ years of QA automation expertise to this work. The practical goal is clear visibility into what's covered, what remains at risk, and what could affect the release.
Readiness is a pipeline property, not a meeting opinion. The final decision should follow the evidence, with human judgment reserved for clearly stated trade-offs.
We design and implement complete test automation systems covering critical journeys, functional, AI, security, and performance testing, with CI/CD integration and clear release-risk reporting. Visit AskYourQA to book a free 20-minute call where we'll map your critical flows and identify which release gates to automate first.